Analyze Large CSV Exports
Your business generates thousands of CSV files from transactions, reports, or operational systems. Convert them into compressed Parquet for efficient storage and analytics.
CSV → Parquet
Convert CSV and JSON into analytics-ready Apache Parquet. Optimize existing Parquet datasets, schemas, compression, and multi-level partitioning through a simple web UI.
A lightweight, high-performance engine running entirely in your AWS environment.
No complex ETL pipelines required.
Starting at $0.25/hour + AWS infrastructure costs.
Free Trial* We also offer private AMI deals via direct contract.
Delivery methods:
From growing data exports to analytics-ready datasets, Parqify helps you prepare and optimize data without building complex ETL pipelines.
Your business generates thousands of CSV files from transactions, reports, or operational systems. Convert them into compressed Parquet for efficient storage and analytics.
CSV → ParquetYour applications produce JSON events, logs, and activity records. Transform them into structured, columnar datasets for reporting and analysis.
JSON → ParquetQueries scan more data than necessary. Organize datasets with date-based partitioning and efficient compression to help analytics engines read less data.
Partitioning & CompressionAlready using Parquet? Reprocess existing datasets to refine schemas, compression, and partitioning for engines like Athena, Spark, and Trino.
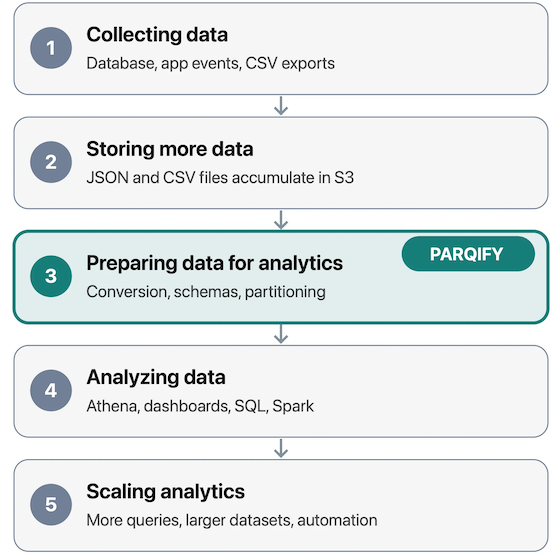
Parquet → ParquetParqify is most relevant at the transition from storing raw data to preparing it for analytics.
It can also help improve existing Parquet datasets.
Poor partitioning and incosistent file layouts make engines like Athena read more than they need to.
Storage costs keep growing.
Query costs increase with scanned bytes.
Transfers and reads take longer.
Queries take longer as data grows.
Text formats force engines to read and parse more data.
Costs rise with scanned bytes.
In query engines that support it, Parquet enables predicate pushdown and column pruning, which can significantly reduce scanned data and improve query performance.
CSV and JSON structures can drift over time.
Manual schema maintenance is brittle.
Mismatched fields can break downstream jobs.
Complex pipelines for a straightforward task.
Operational overhead you may not need.
Longer setup and maintenance cycles.
The Gold Standard for Modern Data Architecture
In the world of Big Data, how you store your information is just as important as the information itself. Parquet is an open-source, columnar storage format designed for maximum efficiency, lightning-fast queries, and seamless scalability.
Performance Meets Efficiency
Traditional formats like CSV and JSON are row-based, forcing engines to read entire files just to access a single column. Parquet flips the script.
Parqify automates schema inference while giving you full control over your Parquet data types.
Organize Parquet datasets for efficient querying with multi-level, Hive-style partitioning.
Fine-tune compression settings to balance storage efficiency, processing speed, and query performance.
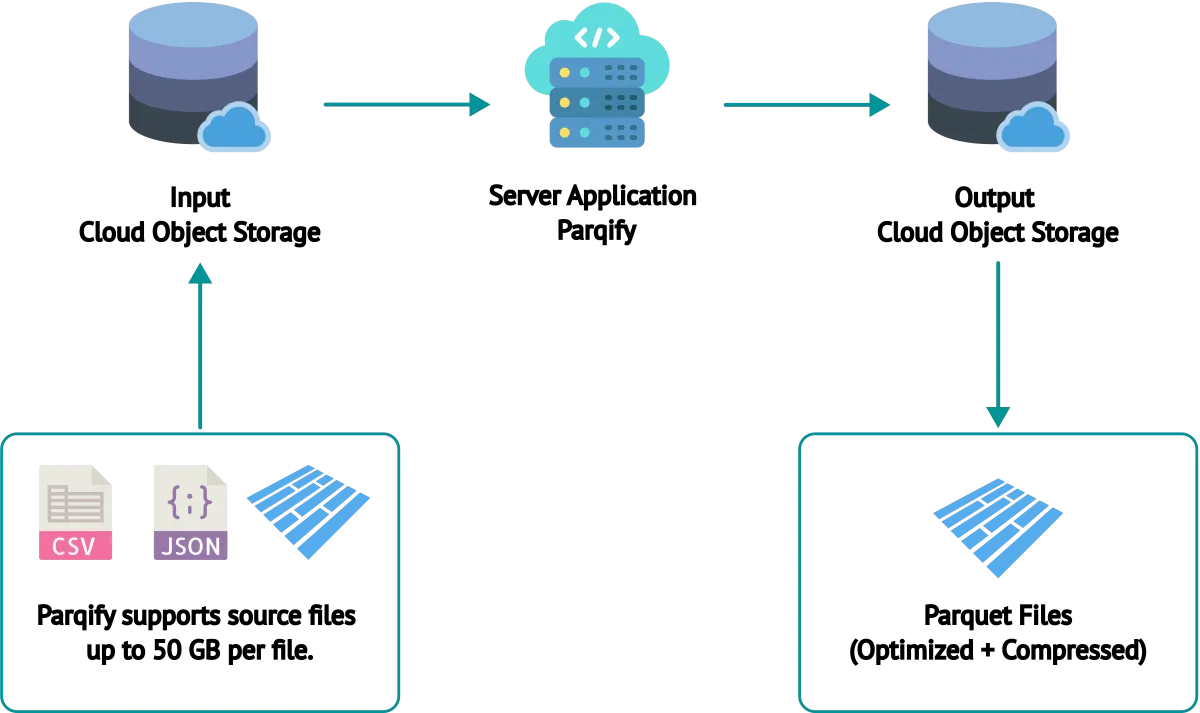
Parqify provides a server application, packaged as an AMI, that customers can deploy within their cloud environment.
This server reads CSV, JSON, and Parquet files from a specified cloud object storage location.
It converts CSV and JSON files to Parquet, optimizes existing Parquet files, and writes the processed files back to a destination storage location.
Parqify uses a lightweight streaming pipeline designed specifically for cloud object storage → Parquet conversion.
Unlike Spark-based tools, it avoids cluster startup, staging datasets, and JVM overhead. Files are streamed directly from cloud object storage into Parquet writers with column-aware buffering and parallel IO.
The results:
Perfect for anyone who just needs Parquet — without building ETL infrastructure.
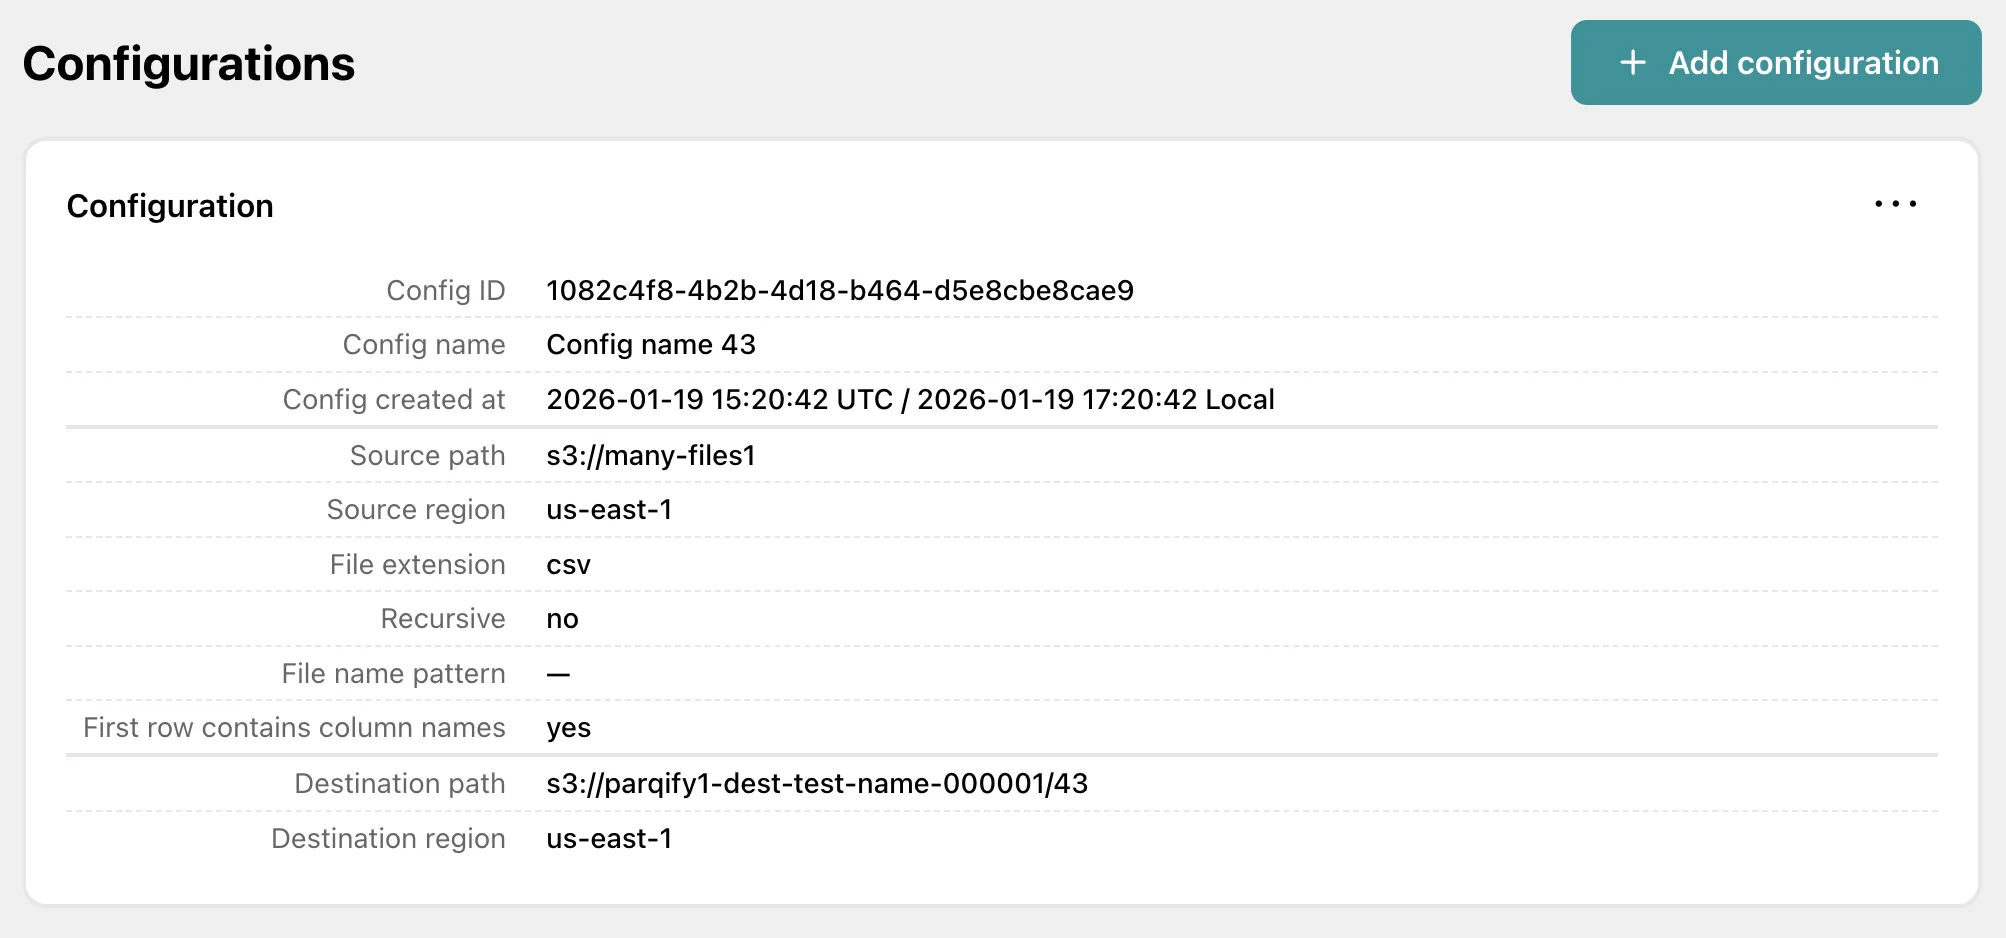
Create, edit, import/export conversion configs.
Configure S3 bucket names, file prefixes, and other conversion parameters through a simple web interface.
Parqify is engineered to be the fastest bridge between raw data and Parquet.
Parqify is designed to utilize as much of the machine instance's capacity as possible to minimize conversion time.
Parqify process large datasets efficiently by converting multiple files concurrently.
Parqify is designed to utilize as much of the machine instance's capacity as possible to minimize conversion time.
We don't believe in idle resources.
Speed is Savings. By maximizing instance capacity and leveraging Rust’s efficiency, Parqify reduces the compute time required for every job. You get your Parquet files faster, and your infrastructure works harder for you.